Attack surface management is the continuous process of finding every exposed digital asset from an attacker's point of view, then prioritizing and fixing the ones that actually matter. It replaces periodic, incomplete inventories with an ongoing feed of validated risk. Done right, ASM turns unknown exposures into a ranked, actionable remediation queue instead of a static report nobody reads.
TL;DR:
- Attack surface management continuously identifies and validates all digital assets, focusing on those exploitable by external attackers rather than just known vulnerabilities.
- It combines external reconnaissance with internal cloud data to reveal shadow resources, misconfigurations, and emerging AI-related exposures.
- Prioritization relies on exploitability and business impact, with validation steps to prevent alert fatigue from false positives.
- Effective controls include endpoint hardening, strict identity management, network segmentation, and proactive DevOps hygiene, applied systematically.
- Building an ASM program requires clear scope, team ownership, deliberate tool selection, automated workflows, and phased expansion to avoid shadow accounts and stale assets.
Table of Contents
- What is attack surface management and how does it differ from vulnerability management?
- What are the different types of attack surface?
- How does the ASM lifecycle actually work?
- What concrete controls actually reduce your attack surface?
- How do you build an attack surface management program from scratch?
- What blind spots do practitioners actually run into?
- Where is attack surface management actually heading?
- Turn attack surface findings into fixes, not backlog
- Sources
- FAQ
What is attack surface management and how does it differ from vulnerability management?
Attack surface management is a continuous cycle of discovery, classification, prioritization, remediation, and monitoring, built around how an attacker actually sees your organization. Wiz defines it as the ongoing process of discovering, classifying, validating, and remediating every digital asset and exposure an attacker could target. The "continuous" part is the whole point. Attackers don't wait for periodic scan windows, and neither should your defence.
ASM works by combining outside-in and inside-out data. Outside-in discovery mimics what an attacker sees when they run reconnaissance against your domains, IP ranges, and public certificates. Inside-out data comes from your own cloud APIs, identity systems, and CI/CD pipelines, giving context that raw external scans can't provide on their own. Palo Alto Networks frames this combination as the way ASM closes visibility gaps that traditional point-in-time tools miss entirely.
Where ASM gets confused is in how it relates to disciplines that already exist inside most security programs. It doesn't replace them. It fills the gaps between them.
- Vulnerability management finds and scores known flaws on known assets. ASM finds the assets vulnerability scanners never knew existed in the first place, including shadow cloud resources and forgotten SaaS integrations.
- CSPM (Cloud Security Posture Management) checks cloud configurations against policy baselines. ASM pulls that same misconfiguration data into a broader picture that includes external exposure and identity risk.
- CAASM (Cyber Asset Attack Surface Management) builds an internal asset inventory from existing tools. ASM adds the outside-in attacker view CAASM tools typically lack.
- Penetration testing validates specific attack paths at a fixed point in time, usually once or twice a year. ASM runs continuously and feeds pen testers a current, prioritized target list instead of a stale asset spreadsheet.
Think of vulnerability management as answering "what's broken on what I know I own," while ASM answers "what do I actually own, and what can someone outside actually reach." Both questions matter. Neither one answers the other.
What are the different types of attack surface?
Security teams tend to picture "attack surface" as just internet-facing servers. That's one slice of a much bigger picture, and the parts people forget are usually where breaches start.
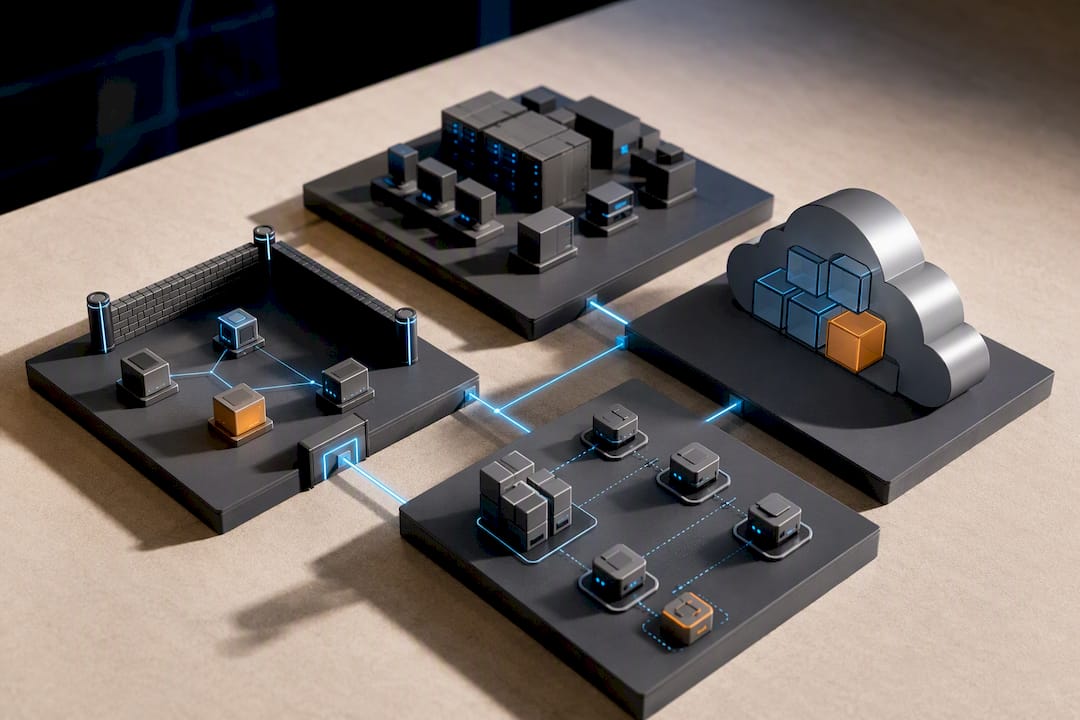
External attack surface covers everything visible from the outside: registered domains, IP ranges, TLS certificates, exposed web applications, and public APIs. Certificate transparency logs and DNS records routinely surface subdomains security teams forgot they owned, sometimes years after a project shut down.
Internal and cloud attack surface includes misconfigured storage buckets, over-privileged identities, and the lateral movement paths those privileges create once an attacker lands inside. A single overly permissive IAM role can turn a minor foothold into full account compromise.
AI and ephemeral workload attack surface is the newest category, and it's growing fast. Exposed inference endpoints, API keys baked into container images, and training data with sensitive information embedded are all showing up in incident reports that didn't exist five years ago.
Human and social engineering attack surface covers phishing susceptibility, credential reuse, and insider risk, none of which show up in an asset scanner but all of which show up in breach statistics constantly.
Physical attack surface includes unmanaged devices, unsecured network jacks, and hardware that leaves the building without proper wiping.
- External: domains, IP ranges, certificates, web apps, APIs
- Internal/cloud: misconfigurations, over-privileged identities, lateral movement paths
- AI/ephemeral: exposed inference endpoints, embedded secrets, training data exposure
- Human/physical: phishing, credential reuse, insider risk, unmanaged devices
A mature program maps all five categories, because attackers don't respect the boundary lines security teams draw between them.
How does the ASM lifecycle actually work?
The ASM lifecycle runs in five connected stages, and skipping any one of them turns the whole exercise into a data collection project instead of a risk reduction program.
- Discovery. This starts with outside-in scanning: DNS enumeration, WHOIS records, certificate transparency logs, and internet-wide port scanning to find what's actually reachable. It pairs with inside-out inventories pulled from cloud provider APIs (AWS, Azure, Google Cloud) to catch assets that never touch the public internet directly but still carry risk.
- Context enrichment. Raw asset lists mean little without ownership, identity permissions, network connectivity, data sensitivity, and CI/CD provenance attached. A public S3 bucket owned by a marketing intern's forgotten side project ranks very differently from one holding customer payment data.
- Risk-based prioritization. This is where most programs go wrong. CVSS severity alone tells you almost nothing about real risk. What matters is exploitability, blast radius, and business impact. IBM's ASM guidance is direct about ranking by attackability and business consequence over raw score. Mapping how an asset's identity permissions and network connections could let an attacker move laterally, sometimes called asset graphing, turns a theoretical CVE into a concrete "if this falls, here's what else falls with it."
- Remediation. Automated ticket creation into existing systems, CI/CD gates that block risky deployments before they ship, and configuration fixes pushed through infrastructure-as-code pipelines all beat a spreadsheet emailed to a dev team once a month.
- Continuous monitoring and validation. Mandiant's ASM approach runs active, benign checks against discovered assets to confirm whether an exposure is actually exploitable, not just theoretically present. That validation step is what separates a useful alert from noise.
Pro Tip: Validation is the bridge between discovery and prioritization. Pair active benign checks with internal access context before you rank anything by severity, or you'll spend your team's time chasing exposures that were never reachable in the first place.
Alert fatigue kills ASM programs faster than any technical gap does. If every discovered asset generates a ticket regardless of exploitability, security teams tune out within weeks. Feeding validated, context-enriched findings into SIEM, SOAR, and ticketing systems keeps the signal-to-noise ratio workable and lets analysts trust what shows up in the queue.
What concrete controls actually reduce your attack surface?
Reducing attack surface isn't abstract. It comes down to a specific set of controls that shrink what's reachable, what's over-privileged, and what's misconfigured, all applied consistently rather than in a burst before an audit.
Endpoint hardening with ASR rules. Microsoft Defender's attack surface reduction rules constrain risky behaviours like Office apps launching child processes or scripts downloading executable content. Microsoft's own documentation recommends testing every rule in audit mode before flipping it to block, because a rule that blocks a legitimate business workflow causes its own kind of incident. Deployment needs proper tooling too. Intune or Configuration Manager handle staged rollouts far better than manual PowerShell pushes across a large fleet, and ASR rules also require Defender Antivirus active with cloud-delivered protection enabled to function fully.
Identity and access controls. Multi-factor authentication, least-privilege role assignment, and regular rotation of service account credentials close off the identity paths attackers rely on once they get past the perimeter. Stale service accounts with standing admin access are one of the most common findings in any serious attack vector analysis.
Network and cloud controls. Segmentation limits lateral movement, private endpoints keep cloud services off the public internet, and web application firewalls filter malicious traffic before it reaches vulnerable code. CSPM remediation closes the configuration drift that accumulates as cloud environments grow.
DevOps hygiene. Infrastructure-as-code scanning, secret scanning in repositories, and pipeline guardrails catch exposure before it ships rather than after a scanner finds it in production.
Operational hygiene. Clear asset ownership, prompt decommissioning of orphaned resources, and tight review of third-party access all shrink the surface without needing new tooling at all.
- Enable ASR rules in audit mode first, then move to block after validation
- Enforce MFA and rotate service credentials on a fixed schedule
- Segment networks and shift public services behind private endpoints
- Scan infrastructure-as-code and secrets before every deployment
- Decommission orphaned cloud resources on a regular cadence
Organizations that pair endpoint-level malware defences with identity controls and cloud configuration management consistently shrink the number of exploitable paths available to an attacker, even without adding new detection tools.
How do you build an attack surface management program from scratch?
Rolling out ASM works best as a staged program, not a single tool purchase followed by hope.
- Define scope and success metrics first. Decide which business units, cloud accounts, and subsidiaries are in scope, then set metrics that actually mean something: asset coverage percentage, mean time to detect a new exposure, and mean time to remediate once it's validated.
- Assign owners across teams. ASM touches security, cloud engineering, DevOps, and infrastructure simultaneously. Without a named owner for each workflow, findings sit in a queue that nobody feels responsible for clearing.
- Pick tool categories deliberately. You generally need outside-in external ASM coverage, inside-out CSPM or CAASM visibility, and a validation layer that confirms exploitability before anything reaches a developer's inbox.
- Automate the feedback loop. Push findings into existing ticketing systems and, where possible, gate CI/CD pipelines so a risky change gets flagged before it merges rather than after it's live. This is also where managed detection integration pays off, since ASM output feeds directly into response workflows.
- Pilot small, then expand. Start with one business unit or one cloud account, tune the noise level, prove the remediation SLA is achievable, and then scale coverage outward.
Pro Tip: Set your remediation SLA before your first pilot ends, not after. Teams that wait to define "how fast is fast enough" almost always end up negotiating it under pressure during an actual incident.
Cross-functional buy-in matters more than tool selection here. A security team with the best external scanner in the market still fails if developers see remediation tickets as low-priority noise dropped into a backlog they never check.
What blind spots do practitioners actually run into?
Shadow cloud accounts spun up by individual teams without security's knowledge remain one of the most common findings in real ASM engagements, right alongside stale identities that outlived the employees who created them. Forgotten subdomains from abandoned marketing campaigns and leaked API keys sitting in public code repositories round out the usual list of surprises.
The fix isn't more scanning. It's developer alignment. Small, specific remediation tickets close faster than one massive backlog dump, and tagging resource ownership directly in infrastructure-as-code templates means nobody has to hunt down "who owns this" during an active incident.
- Audit for shadow cloud accounts outside central identity management
- Flag identities tied to departed employees or decommissioned projects
- Search for forgotten subdomains and expired but still-resolving DNS entries
- Scan public repositories for leaked keys and credentials on a recurring basis
Where is attack surface management actually heading?
ASM is moving away from point-in-time scanning and toward continuous validation built directly into how developers already work. That shift is overdue. A monthly scan report has never stopped a breach that happened on day 12.
For 2026, the priorities that matter most are managing AI-related exposures as inference endpoints multiply, reducing blast radius through better privilege mapping, and instrumenting CI/CD pipelines so remediation happens before code ships rather than after a scanner catches it in production.
— Nick - Sr. Executive
Turn attack surface findings into fixes, not backlog
Most security teams don't lack visibility tools. They lack the staff hours to validate every finding, chase down asset owners, and push fixes through before an attacker beats them to it. Managed attack surface management can be offered as part of a consolidated service, so discovery, validation, and remediation tickets flow into the tools your team already uses instead of creating a second dashboard nobody checks.
It means that real-time threat detection, cloud infrastructure management across major cloud providers, and compliance work for standards like SOC 2 and HIPAA can sit under one contract with one point of accountability, rather than multiple vendors pointing fingers at each other during an incident. If your current setup means chasing five different tools to answer "what's actually exposed right now," book an assessment through the AccountNext-Nexus services page and find out what a consolidated, continuously managed program actually looks like for your environment.
Sources
- Attack surface reduction rules overview — Microsoft Docs
- Attack Surface Management: A Practical Guide — Wiz
- What is Attack Surface Management? — IBM
FAQ
What are the three key components of attack surface monitoring?
Continuous monitoring, attacker-perspective discovery combining outside-in and inside-out data, and risk-based prioritization built on exploitability and blast radius rather than raw severity scores.
How do you minimize your attack surface?
Enable endpoint controls like Microsoft's ASR rules in audit mode before block, enforce MFA and least privilege, segment networks, and decommission orphaned cloud resources on a set schedule.
What is the difference between SIEM and UTM?
A SIEM aggregates and correlates security event logs from across an environment for detection and investigation, while a UTM (Unified Threat Management) appliance bundles perimeter defences like firewall, antivirus, and intrusion prevention into a single network device. ASM findings typically feed into a SIEM for correlation, not into a UTM.
Is APT a form of malware?
No. APT stands for Advanced Persistent Threat, which describes a sustained, targeted attack campaign, often carried out by a specific threat actor group, rather than a single piece of malicious software. An APT campaign may use several types of malware as tools within a longer operation.
How is ASM different from a one-time penetration test?
A penetration test validates specific attack paths at a fixed point in time, usually annually. ASM runs continuously, feeding validated, prioritized exposure data to security teams year-round rather than in a single snapshot.